
Data scraping
Web scraping and data extraction at real volume
Google Search, Google Maps, marketplaces, real-estate listings or any custom source, delivered as a clean HTTP API or a dataset your team can use without thinking about proxies or CAPTCHAs.
Public data is valuable, and hard to collect reliably
The data you need is usually already public: competitor prices, listings, reviews, search results, business directories. Collecting it once is easy. Collecting it every hour, at scale, while sites change their markup and block your IPs, is engineering.
We run scraping pipelines as production systems: rotating proxies, CAPTCHA solving, headless browsers where needed, schema validation on every record, retries, and alerts when a source changes. You get the data. We keep the pipeline alive.
Who it's for
A good fit when
- You monitor competitor prices or stock across marketplaces and online shops.
- You need leads or business data from Google Maps, directories or social platforms.
- You are building a product on top of search results, listings or public records and need a dependable data feed.
Deliverables
What we deliver
Google Search and Google Maps scrapers
Rankings, ads, local packs, business profiles, reviews and contact details, by keyword and location, at the volume you need.
Marketplace and e-commerce data
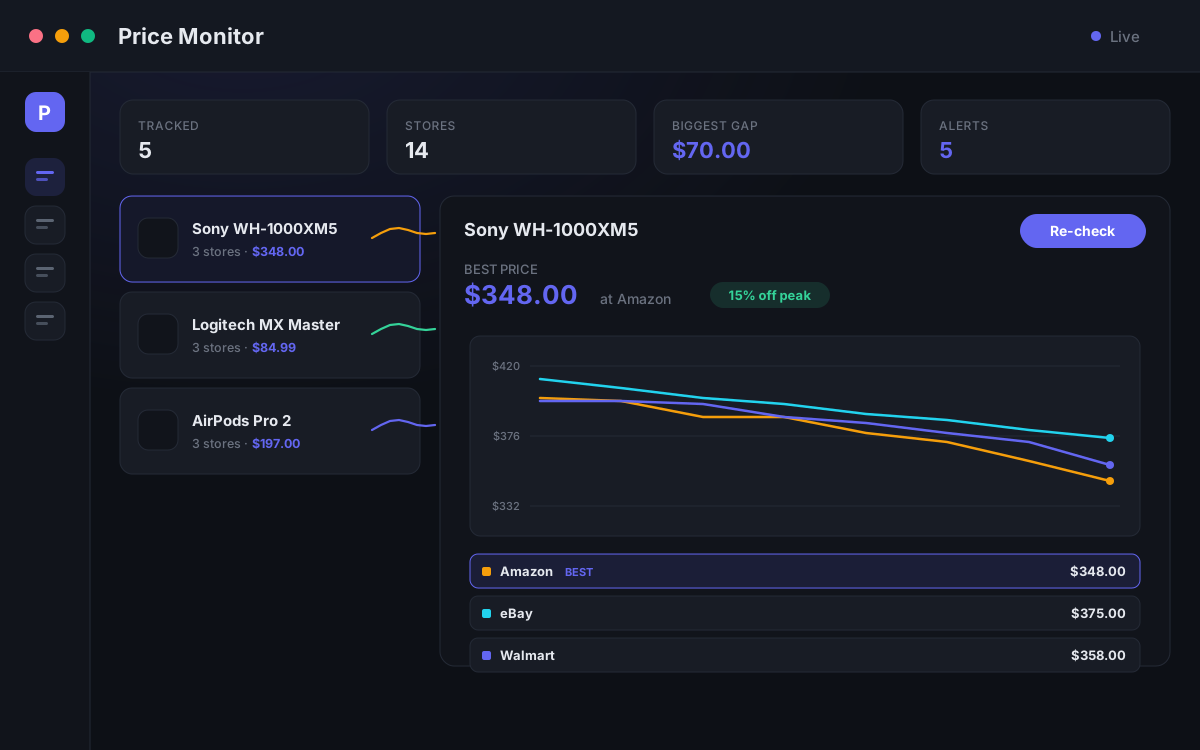
Prices, stock, variants, sellers and reviews from Amazon, Digikala, Noon, eBay and regional shops, normalized into one schema.
Real estate and classified listings
New listings, price changes and removals tracked over time, with deduplication across portals.
Anti-bot handling
Residential and datacenter proxy rotation, CAPTCHA solving, browser fingerprinting and rate control, so blocks do not become your problem.
Delivery your way
A REST API, scheduled exports to CSV, Google Sheets or your database, or a dashboard with alerts on the changes that matter.
Monitoring and maintenance
Source changes are detected and fixed by us, usually before you notice. Uptime and freshness are reported, not assumed.
Process
How a scraping project runs
 Python
 Scrapy
 Playwright
 Puppeteer
 PostgreSQL
 Redis
 Docker
 FastAPI
- 01
Source and field review
We check each target site, the fields you need, the volume, the legal position and the refresh rate, and quote from that.
- 02
Prototype on real pages
A first extractor runs on live pages within days, so you see actual records and adjust the schema early.
- 03
Scale and harden
Proxies, concurrency, retries, validation and storage are added until the pipeline runs unattended at your volume.
- 04
Deliver and operate
The API or export goes live with documentation, and we keep the extractors current as sources change.
Related work
Work like this
Further reading
Guides on this topic
How to Monitor Competitor Prices with Web Scraping
A practical guide to competitor price monitoring: sources, product matching, refresh rates, anti-bot defences, alerts and running costs.
September 27, 2026Google Maps Lead Scraping: What Is Possible and Legal
What data Google Maps has, the Places API versus scraping, what Google's terms and privacy law say, and how to build a lead list responsibly.
FAQ
Questions we hear
Collecting publicly available data is lawful in most jurisdictions when it respects the site's terms, robots rules, rate limits and personal-data law. We review each source before quoting, and we do not scrape behind logins, paywalls or personal data without a clear legal basis.
Proxy rotation, realistic browser sessions, request pacing and, where needed, CAPTCHA-solving services. Every pipeline has retry logic and alerting, so a block is handled rather than silently dropping data.
From daily to every few minutes, depending on the source and your budget. Price monitoring typically runs hourly, search rankings daily, and listings on change detection.
Whatever fits your workflow: a documented REST API, files pushed to your storage, rows in your database, a Google Sheet, or a dashboard with alerts.
Yes. Right-to-left content, Persian and Arabic numerals, Jalali dates and local marketplaces such as Digikala, Torob, Divar, Noon and Haraj are sources we already handle.
Need a data feed that never stops?
Tell us the sources and the fields. We will check feasibility and send a plan within a business day.